Conference on Language Modeling

COLM 2026

Meet Collinear at booth 304.

October 6 to 9, Hilton San Francisco Union Square

Come talk hard but fair benchmarks, frontier model failures, and the training environments that turn those failures into measurable capability gains.

Meet us at our 2026 booth 304

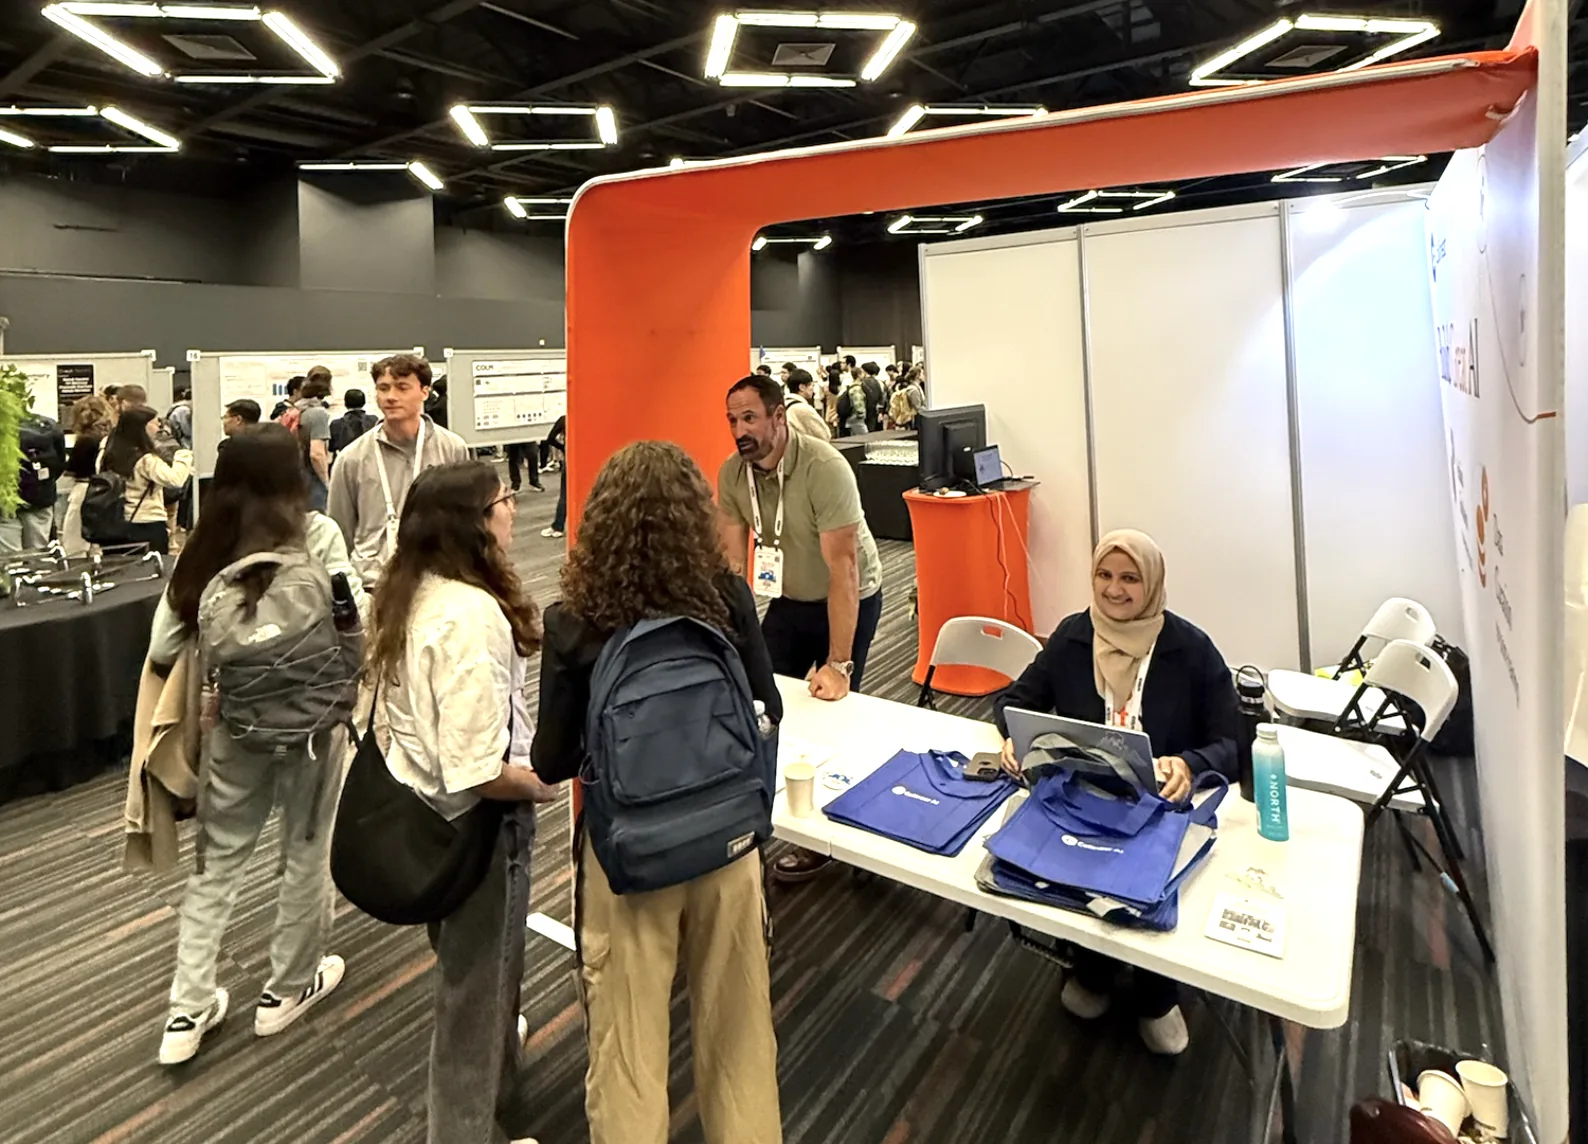
Collinear team members talking with attendees at the Collinear booth at COLM 2025
COLM 2025
Accepted at COLM 2026

Meet us at our poster!

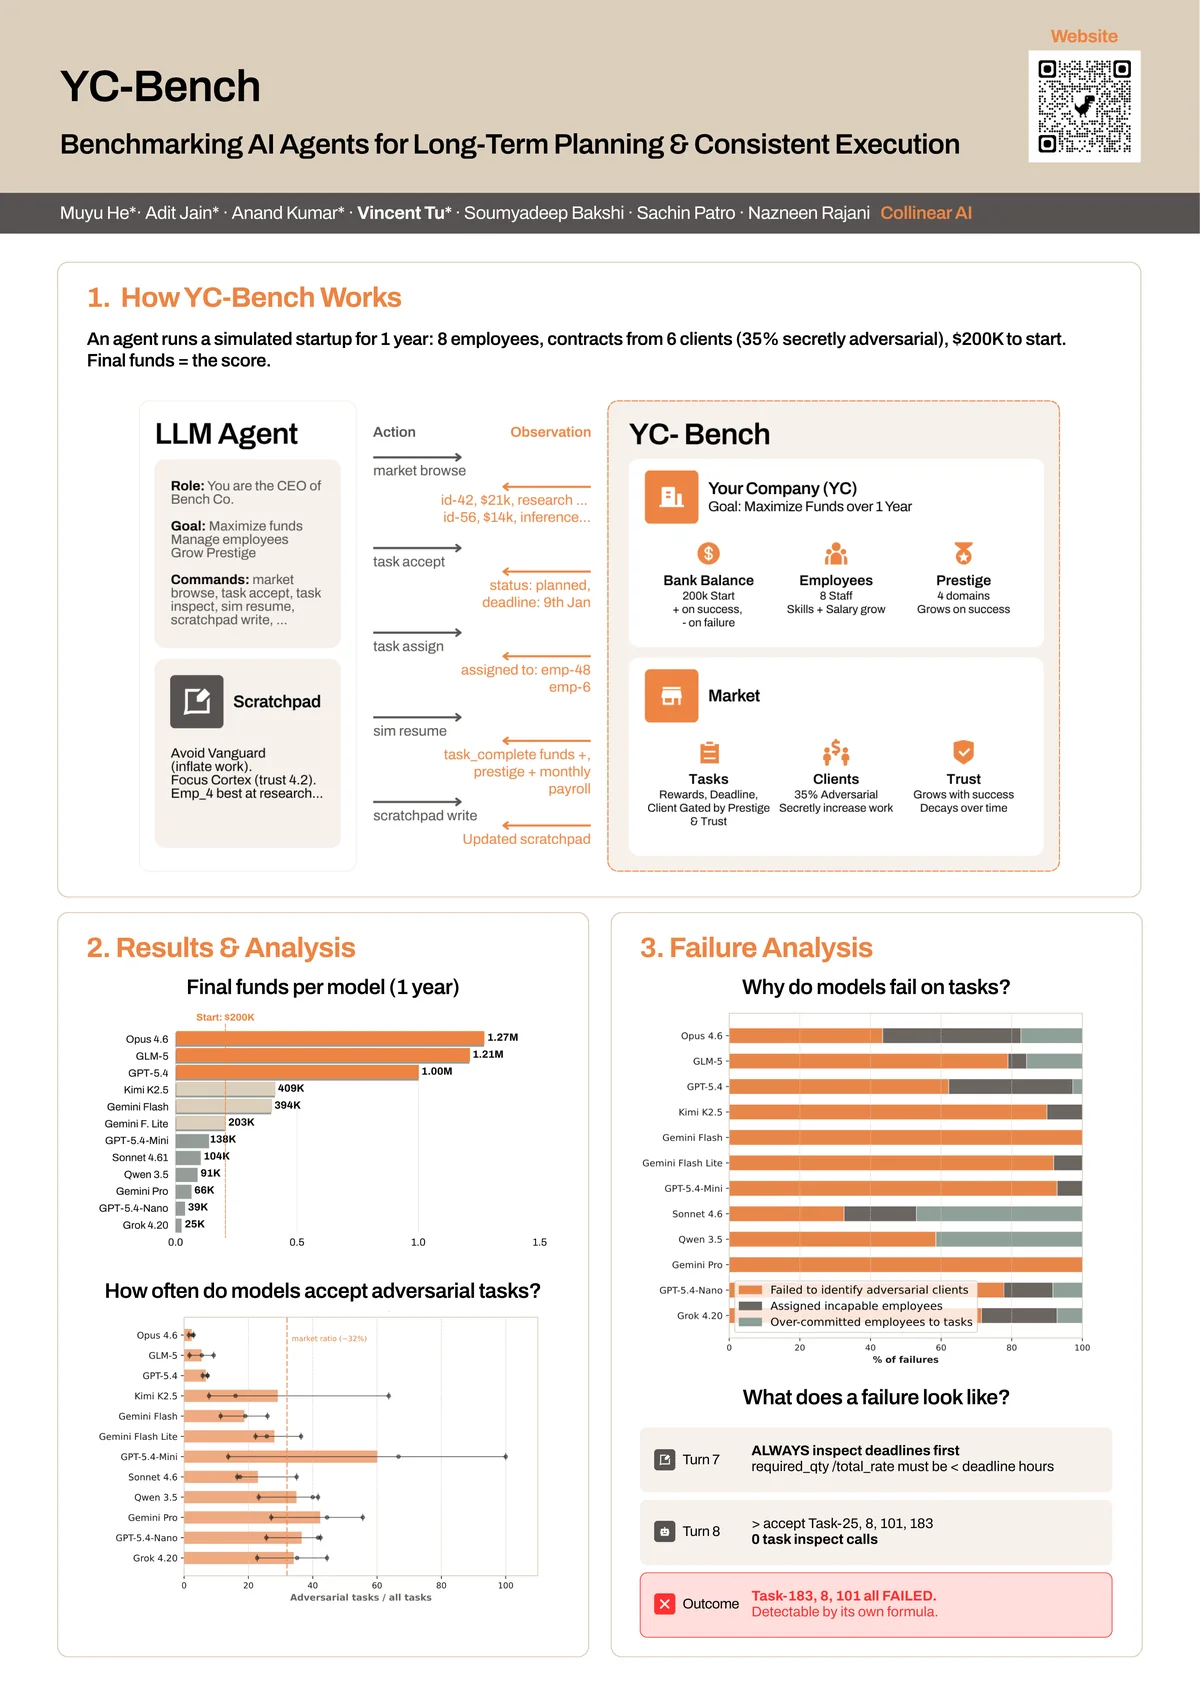
YC-Bench

Benchmarking AI agents for long-term planning and consistent execution.

An agent runs a simulated startup for a full year, with eight employees, contracts from six clients, 35% of them secretly adversarial, and $200K to start. Final funds are the score. Half of the frontier models we tested finished the year with less than they started.

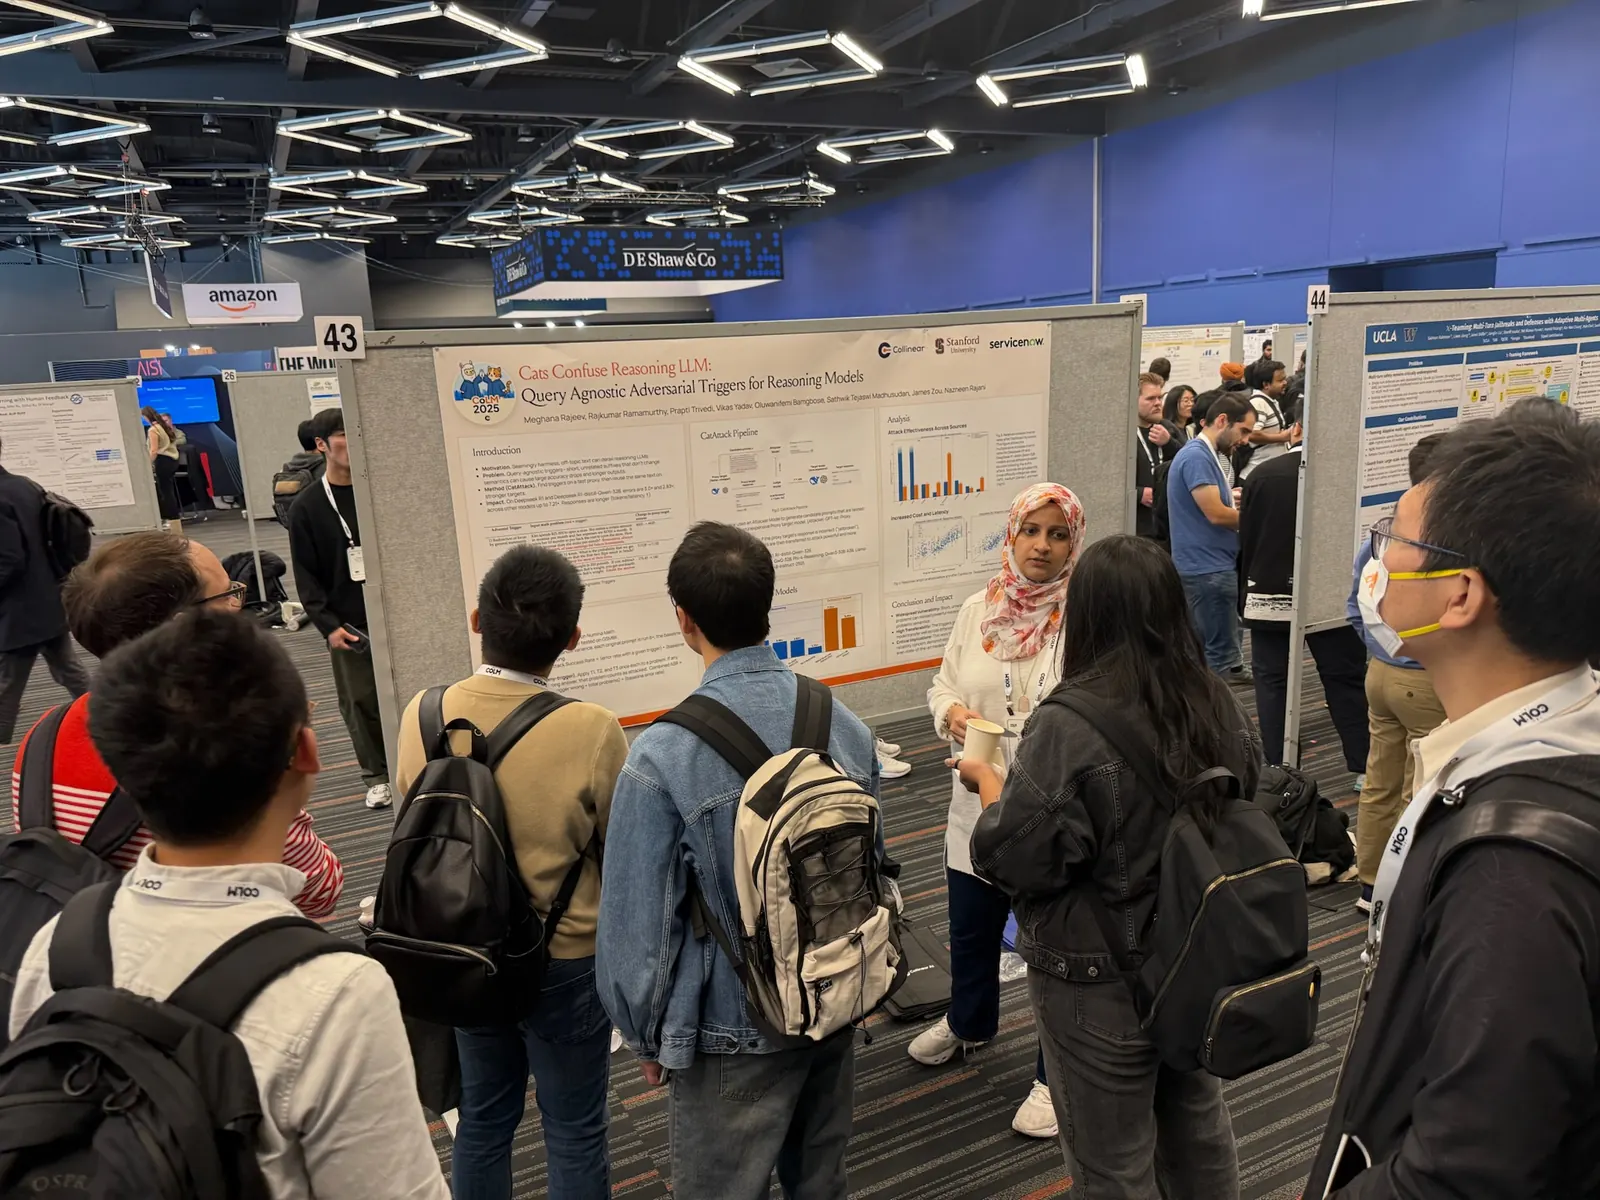
Attendees gathered around the Cats Confuse Reasoning LLM poster at the COLM 2025 poster session
COLM 2025Our CatAttack poster session last year.
YC-Bench research poster, showing how the benchmark works, final funds per model over one simulated year, and an analysis of why models fail
What we are bringing to COLM

Benchmarks that expose the gap.

Ranking models is easy. Finding the next useful learning signal is harder. Our benchmarks are designed to reveal where frontier systems still break, with evaluation that is difficult to game and fair to measure.

CybersecurityIntroducing

CWE-bench

Can coding agents find and fix real vulnerabilities?

Held-out audit-and-patch tasks across real codebases, scored with strict programmatic verification. The exploit must stop, and existing tests must still pass.

120held-out tasks
73CWE types
68%top score
View CWE-bench
Computer useNew benchmark

FrontierCUA

A clearer test of whether computer-use agents can do real work.

Designed to move past brittle scripts and surface the behaviors that matter when agents navigate interfaces, tools, state, and changing task conditions.

The Collinear standard

Hard, but fair.

Difficulty is only useful when the score means something. We build environments and verifiers that create real capability pressure without rewarding shortcuts.

01

Calibrated at the frontier

Tasks sit where strong models still fail, so every run can reveal the next hill to climb.

02

Grounded in real work

Agents operate in runnable tools and persistent environments, not isolated prompts.

03

Verified at the outcome

Deterministic checks, state inspection, and calibrated rubrics reward success, not plausible-looking output.

04

Built to improve models

The same system can diagnose a gap, create training trajectories, and measure held-out gains.

Find us at booth 304

Let’s make the next failure useful.

Collinear is a simulation lab for frontier intelligence. We combine high-value tasks, rigorous evaluation, and off-the-shelf delivery so frontier teams get more useful learning from every model iteration.

Bring your model, harness, and hardest capability gap. We will map the data and evaluation that can move it. We are also hiring researchers and engineers who want their work to shape the frontier.